
How to choose the right AI for your product (without falling for the hype)
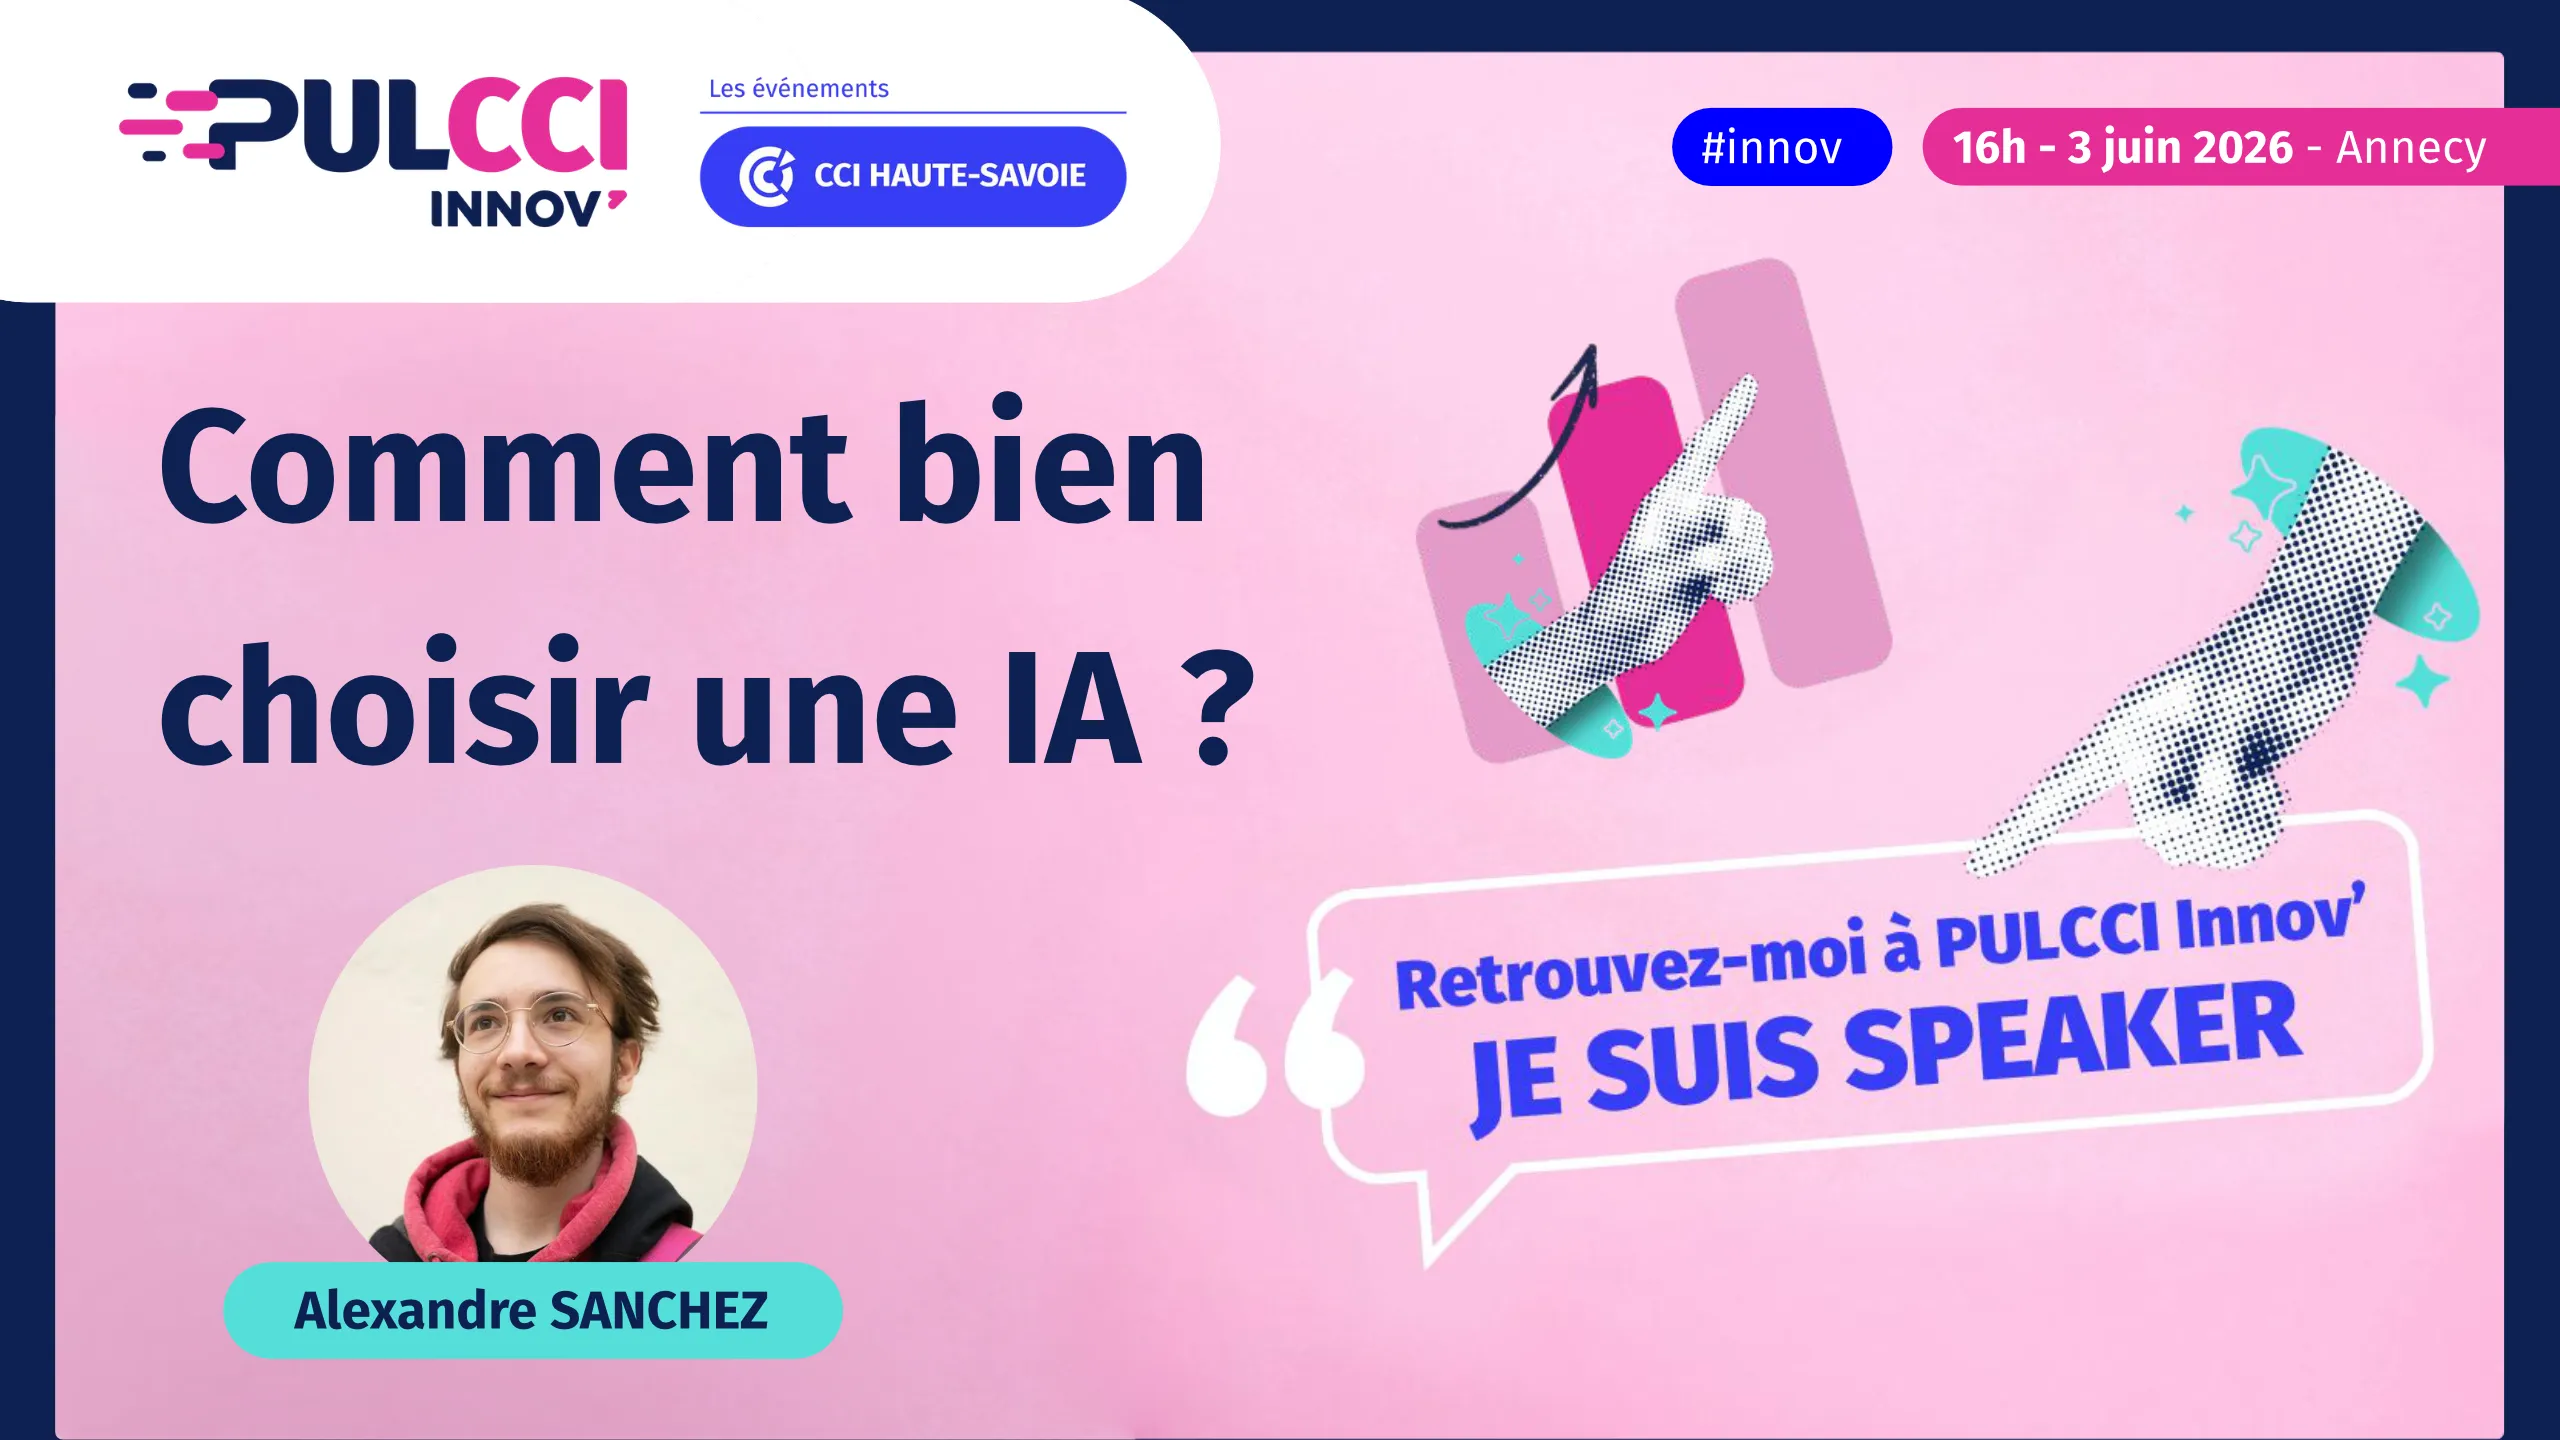
As part of PULCCI Innov’: come and chat with us!
This article is a taste of what we’ll be presenting in more detail at the PULCCI Innov’ event. It’s precisely to share our analysis method and our field-tested insights on AI integration that we’ll be hosting a dedicated talk there.
Join us on Wednesday, June 3 at 4 PM (CEST) for our session: “How to choose the right AI?”.
This talk has been designed from start to finish to be accessible to decision-makers and non-technical profiles. No incomprehensible jargon and no debates about neural network architecture. We’ll share with you:
- Our “anti-hype” filter to frame your needs.
- How to anticipate the trap of per-token billing.
- Concrete comparisons (Cloud vs. Local, Specialist vs. Generalist).
Practical information:
- 📍 Location: CCI Haute-Savoie (the local Chamber of Commerce and Industry), 5 Rue du 27e BCA, 74000 Annecy, France
- 💶 Price: Free, registration required.
- 📅 Dates: The full event takes place over two days, June 3 and 4, 2026.
Organized by the CCI Haute-Savoie, PULCCI Innov’ is packed with exciting workshops for the local tech and business ecosystem.
👉 Discover the program and book your free spot for PULCCI Innov’
A complete resource pack coming soon
At Otterly Space, we deeply believe in open innovation. We know that decision-makers’ days are busy, and that not everyone will be able to travel to Annecy on June 3.
That’s why we’ll be making a complete resource pack available to the public in the days following our talk. It will include:
- 🎥 The full video replay of the talk.
- 📊 Our presentation slides.
- 🛠️ Our exclusive analysis frameworks: the decision matrices we use internally to audit our clients’ projects.
A taste of the talk: the anti-hype method
For many years, we’ve supported the creation and evolution of digital products. If there’s one major challenge we encounter almost systematically with our clients today, it’s the integration of Artificial Intelligence.
Between market pressure, investor expectations, and the fear of missing out, AI has become the magic word every decision-maker feels obliged to add to their roadmap.
We’ve seen many companies try to integrate ultra-powerful AI models without always finding real business relevance. The result? Technical white elephants, exploding operating costs, and complex issues around data sovereignty.
We eventually consolidated a method to avoid these pitfalls.
The syndrome of technology looking for a problem
Integrating AI is a complex field in itself. While APIs like those from OpenAI or Anthropic offer ready-to-use solutions that are impressive at the prototyping stage, the concrete, large-scale implementation often turns out to be more demanding both financially and technically.
Critical questions quickly arise:
- “How do we make sure our users’ data stays confidential?”
- “How do we handle the API bill exploding as our user base grows?”
- “Do we really need a 70-billion-parameter LLM to classify three categories of text?”
The most common mistake is trying to plug in a “hype” technology and then find a use for it. At Otterly Space, our rule is simple: AI is a tool, not an end in itself. If a simple regular expression (Regex) or a classic search algorithm covers 90% of the need for a fraction of the price and with no risk of hallucination, then AI may not be the priority.
Our three framing questions (before writing a single line of code)
When an AI feature idea emerges, we systematically run it through three simple questions. You can make them your own starting today:
- What is your user’s exact problem? What are they trying to accomplish faster or better?
- What is the “AI-free” solution? Very often, a good classic algorithm, well-thought-out filters, or a business-rules system are more than enough.
- What is the real delta brought by AI? It must deliver a massive gain: time, unprecedented personalization, or automating a task that was previously impossible for a machine.
If the answer to the second question already covers 90% of the need, AI is probably not your priority. This is the “anti-hype” filter we’ll detail in depth during the talk, with analysis frameworks to back it up.
The Kelper experience: the operating-phase ROI trap
Let’s illustrate this with a concrete scenario from our own developments: Kelper, our quick-summary app (we go into detail about its design in our dedicated Kelper article).
During the design phase, we had a precise need: enabling voice input to save users time.
Our first reflex (and that of 99% of the industry right now) was to turn to the cloud. We integrated the reference model for transcription: OpenAI Whisper.
On paper, it was perfect and the integration took us barely a few days. However, during our larger-scale tests, we made a twofold observation:
- Operating cost: each transcribed minute cost us $0.006, or about $0.36 per hour (OpenAI API pricing). Taken in isolation, that seems trivial. But multiplied by a base of daily active users, this operating cost (the “Run”) ended up seriously eating into our margin.
- Contextual accuracy: The cloud AI, while powerful, wasn’t always accustomed to our users’ specific verbal tics or regional accents.
The pivot to “On-Device”
So we took a step back to reassess existing solutions without giving in to the all-cloud trend. The answer was right in the user’s pocket: the speech recognition natively built into smartphones.
By switching to this solution:
- Our operating cost dropped to €0 (the computation happens on the device).
- Privacy became absolute (no voice data is sent to our servers).
- Accuracy improved, because the phone’s keyboard is already trained on its owner’s voice.
A word of caution, though: “on-device” is not a universal silver bullet. It remains limited by the power of your user’s device, and hosting your own models can sometimes cost more in servers than using the Cloud APIs of the tech giants (which are often heavily subsidized). This is exactly the kind of “risk-benefit” trade-off that every product decision-maker needs to know how to make today.
A few keys to avoid getting it wrong
The Kelper case is just one example among many. Here are three reflexes we keep in mind on every project, and which we’ll dig into during the talk:
- The specialist over the generalist. To read and extract data from a document (an invoice, an ID), a specialized model (OCR) will often cost as much, or even less, than an ultra-powerful generalist LLM, while offering far better quality.
- Data sovereignty as a criterion, not a detail. Especially in B2B, ask yourself whether your clients’ data can legally transit through American servers, or whether it’s better to favor a self-hosted European open-source AI.
- Real time isn’t always necessary. If a task can be done in the background, grouping your requests into “batches” (batch processing) via the deferred APIs of providers like Mistral or OpenAI can dramatically slash your bill.
We’re deliberately keeping the details of our decision frameworks for the event: that’s where we’ll show you how to apply them concretely, with examples to back it up.
We can’t wait to discuss it with you in person on June 3!
Propels your product to the upper level 🚀
Do you need help to assess your needs and choose the best option for your product? Otterly is there to accompany you and propel your product to the market!